LLM strategy
Overall approach to LLM integration
Korall Engineering™'s approach to integrating Large Language Models safely and effectively.
Did You Know?
Korall Engineering™'s LLM strategy was designed with a specific threat model in mind: "what if the AI hallucinates and tries to drive the machine off a cliff?" The answer is the embedded/strategic barrier - even if the AI generates a perfect-sounding command to "maximize velocity toward coordinates (cliff)", the embedded layer's safety monitors will refuse to execute it.
Core principles
1. Local-first
All node-side LLM runs locally. No internet contact except via Zoo (hole-punching) or Hub.
Agent with local LLM
    │
    ├─► Local inference (no internet)
    │
    └─► Hub connection (if external LLM needed)
            │
            └─► External API (Claude, etc.)
Why: Privacy, latency, offline operation, reduced attack surface.
2. Hub as gateway
External services (LLMs, APIs, models) are accessed only through a trusted Hub node.
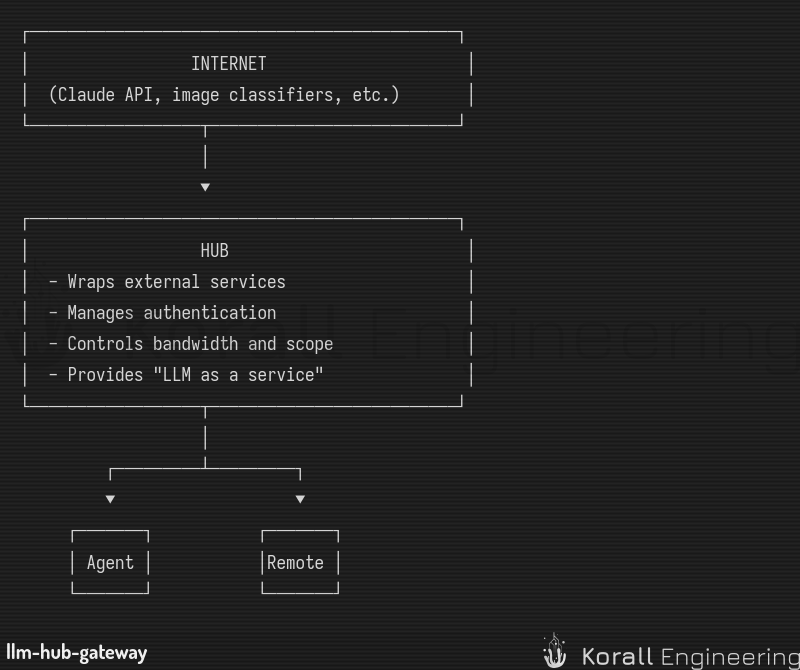
Why: Single security boundary, centralized access control, simplified node requirements.
3. Permission-centric
LLMs operate within explicit, user-granted permissions via OPAL (Operator Permission and Access Layer).
Why: Human authority over AI actions, auditability, safety.
4. Deterministic identity
Agent personalities are RNG-derived from cryptographic keys, ensuring consistency across contexts.
Why: Recognizable node identity, consistent interaction experience.
The embedded/strategic barrier
Korall Engineering™ enforces strict separation between hardware control and AI:
| Layer | Characteristics | LLM Access |
|---|---|---|
| Embedded | Real-time, deterministic, safety-critical | None |
| Strategic | Flexible, creative, latency-tolerant | Full (with permissions) |
LLMs can request "navigate to kitchen" but cannot command "set motor voltage to 12V".
See Embedded/Strategic Barrier for details.
LLM deployment options
Local LLM (agent)
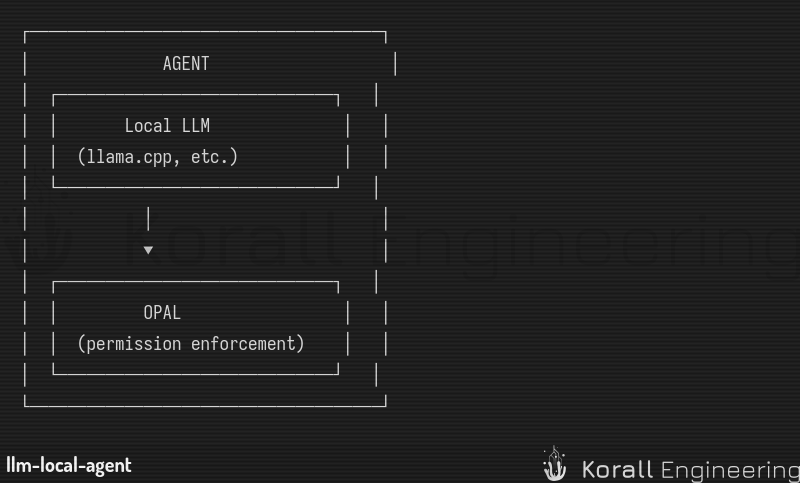
- Runs on agent hardware
- No network required
- Limited by hardware capabilities
- Full privacy
External LLM (via hub)
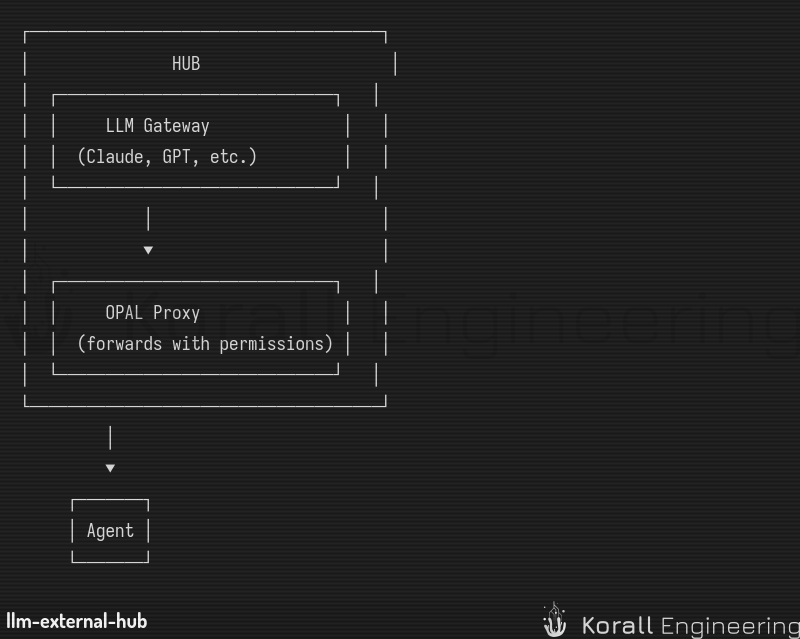
- Powerful models available
- Requires Hub and internet
- Hub manages API keys
- Permissions still enforced
A server of your own
OPAL speaks two provider protocols: Anthropic's own, and the OpenAI-compatible protocol that OpenAI, Google, OpenRouter, Groq and most self-hosted servers speak. A llama.cpp, Ollama, LM Studio or vLLM server on your network is a provider like any other: it has a base URL, a key if you gave it one, and models. The app treats it as self-hosted, so the key is optional, the models cost nothing, and it waits longer for a large prompt. See Use a self-hosted server.
Personality and LLM
When LLMs interact through an agent, personality provides consistency:
Agent Key → Deterministic RNG → Personality Traits
                               ├── Name
                               ├── Voice characteristics
                               ├── Visual identity
                               └── LLM persona prompt
The personality generates a prompt fragment:
You are [Name], a [traits] assistant.
You speak with [voice characteristics].
Your responses should reflect [personality aspects].
This ensures the same node has a consistent identity regardless of which LLM backend is used.