LLM integration
Large Language Model integration design
Strategy and design for integrating Large Language Models with Korall Engineering™ safely and effectively.
Did You Know?
Korall Engineering™'s LLM strategy is "local-first" - your node can run AI on its own hardware (via llama.cpp or similar) without ever contacting the internet. External LLMs like Claude are only accessed through a Hub, which acts as a single security gateway. This means your node keeps working even without internet.
Topics
| Topic | Description |
|---|---|
| Strategy | Overall approach to LLM integration |
| OPAL design | Operator Permission and Access Layer |
| Event flow | How LLM interactions are processed |
Overview
The applications use language models, and keep them safe with:
- Embedded/Strategic Barrier - Clear boundary between real-time control and high-level planning
- Trust-based Permissions - LLM actions bounded by operator-granted permissions
- Auditable Commands - All LLM actions logged and reversible
Key concepts
The safety model
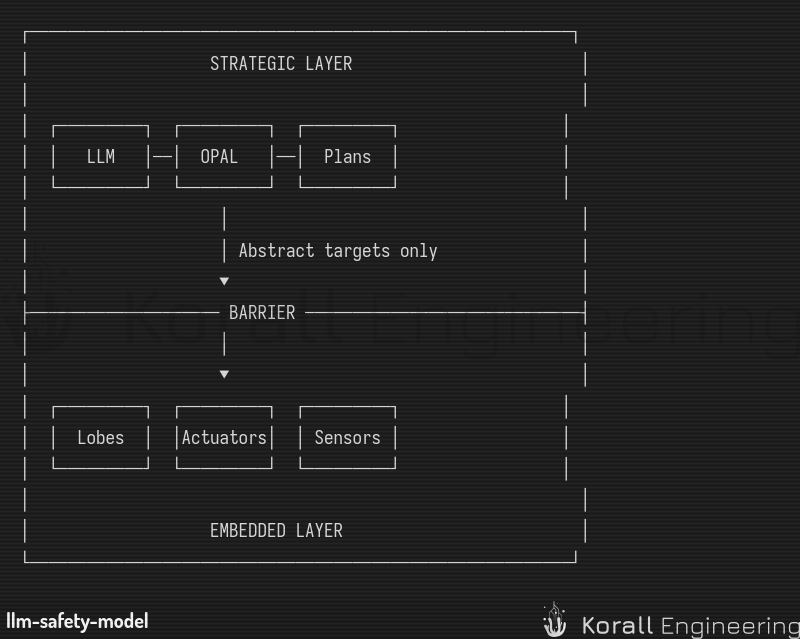
LLMs operate in the strategic layer with full creative freedom, but can only affect hardware through abstract targets that the embedded layer translates safely.
OPAL: the control layer
OPAL (Operator Permission and Access Layer) enables safe LLM control:
- Structured commands - JSON API, not free-form text
- Permission system - Granular, user-controlled access
- Self-documenting - LLMs can discover available commands
- Audit logging - Every action is recorded
Local-first AI
Korall Engineering™ prioritizes local LLM execution:
- Agents can run local LLMs (llama.cpp, etc.)
- No internet required for basic AI features
- External LLMs accessed only through Hub
- Privacy and latency benefits