Read the chat surface
The chat overlay shows more than the conversation. A status line reports what the model is costing you, a selector decides what runs without asking, and the input accepts pictures as well as text. This page covers all three.
The status line
The status line sits on the busy bar, to the right. It reports facts, and it hides anything the provider does not report rather than showing an empty gauge. A blank space means "nobody supplied this number", which is different from zero.
What can appear:
- The model name. The name the provider gave for the last turn when it gave one, and the configured name otherwise. Hover it to see which.
- Tokens spent. Read from the usage record the application already keeps, so this figure and your usage history cannot disagree. Hover for the split between input and output, the number of turns, and the estimated cost.
- A context bar. How much of the model's context window this conversation has used. It fills as the window is spent.
- A quota bar. How far through a rate-limit window the clock is —
5hor7d, with the time left.
Two things the bars do not mean
A bar always fills as something is SPENT, never as headroom. A full bar means "used up", in every bar on this line.
The quota bar measures the CLOCK, not your usage. The provider reports the
window and when it resets, and no spend percentage. So 5h 60% means you are
sixty percent of the way through the window, not that you have used sixty
percent of it. Hover for the reset time.
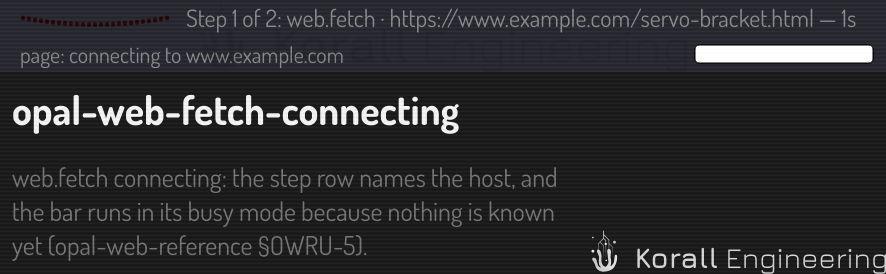
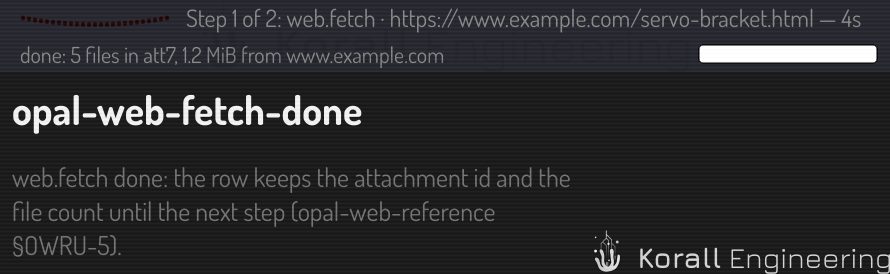
The progress row of a running step
While a plan runs, a step can report how far it has got. The report shows in
a row under the step label: a line of text and a bar. A web.fetch step uses
the row like this:
| The fetch | The row shows |
|---|---|
| Connecting | The host, and a busy bar, because nothing is known yet |
| Receiving, and the host sent the size | The bytes received of that size, and a bar of that fraction |
| Receiving, and the host sent no size | The bytes received, and a bar of the time used of the timeout. The text says so |
| Done | done:, the number of files, the attachment and the size. The row stays until the next step starts |
Stop, under the send button, ends the plan. Usually it lets the running
step finish and then runs no more steps. A step that can end cleanly at once
is canceled at once, and web.fetch is such a step. The tooltip of Stop
says which of the two it does.
Choosing what runs without asking
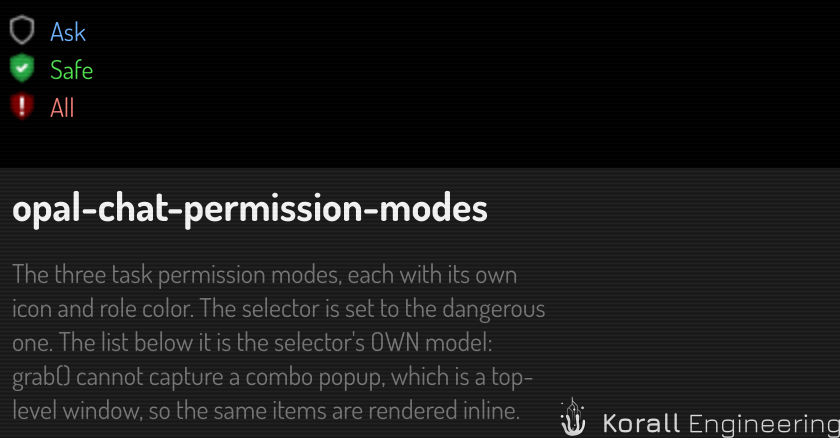
Beside the send button is the permission selector. It decides what happens when the assistant proposes a plan of tasks.
| Mode | What it does |
|---|---|
| Ask | Prompts you before running any plan. |
| Safe | Runs tasks marked safe on its own, and prompts for the rest. |
| All | Runs every plan without asking. |
All is red and carries a warning mark because it removes the last step where you can say no. Each change is written into the conversation, so the transcript always shows which mode a turn ran under. This includes a change that a plan makes.
The task that changes the mode, llm.permission.set, needs the owner tier.
It runs only while the device owner is logged in, and a plan from another node
cannot run it.
The choice is remembered per node. The same setting is a row of the OPAL section of the app's settings page, which OPAL settings in the chat's menu opens. A change in one place shows in the other at once. The menu item is hidden when the app gives the chat no settings page.
From a plan or a script
Two tasks reach the same setting from a plan or from the command line. They act on the running chat overlay:
hub --opal 'llm.permission.get' -c
hub --opal 'llm.permission.set mode=safe' -c
llm.permission.get is worth calling before asking for something destructive:
it tells you whether a plan will run without the user seeing it. A mode outside
the three is refused with the list rather than guessed at.
With no chat overlay running, no mode is in effect. llm.permission.get then
reports overlay=false, and llm.permission.set refuses and changes nothing.
Putting a picture in a prompt
Paste an image, or drag a picture file into the input. Either way it becomes a chip in the text, which you can position, select and delete like a character. Hover a chip to see a larger preview.
The two origins are treated differently, and the chips show it.
- A pasted picture had no file behind it, so one is written into the capture directory. It belongs to the application and can be cleaned up later with the rest of the captures.
- A referenced file is one you already had. It is read where it lies and never copied, changed or removed.
That difference matters when you are freeing space: pruning captures can remove a pasted picture from an old conversation, and will never touch a file of your own.
A chip whose file has disappeared before you send is dropped with a warning, and the turn still goes.
See also
- Use the chat overlay — opening it, docking it, and dropping folders in.
- Troubleshoot errors — when the overlay says it cannot answer.